Paid engagement
AI Reliability Evaluation
A fixed-scope, fixed-price look at what your GenAI application's telemetry actually shows: where operations fail, which provider and model carry the errors and the latency, and which evidence is missing rather than inferred.
This is an evaluation, not a pilot and not a production deployment. The boundary below is part of the offer, not fine print.
What you get
Fixed at engagement start. Anything outside this is re-scoped and requoted, not absorbed.
- Price
- USD $7,500 per AI Reliability Evaluation
- Coverage
- One application or environment
- Data ceiling
- Up to 100 GB of approved telemetry
- Window
- A 10-business-day window
- Delivery effort
- At most 30 delivery hours
- Workspace
- One workspace
- Output
- One versioned assessment and one readout
- Wind-down
- Export and deletion evidence at engagement end
What the evaluation answers
A bounded question set, fixed in advance. Each query carries a stable identifier, a budget, and a result fingerprint, so a finding can be re-run and checked rather than taken on trust.
- Operation volume, error rate, and latency by provider and model.
- Input and output token use, and first-chunk latency, where your telemetry supplies them.
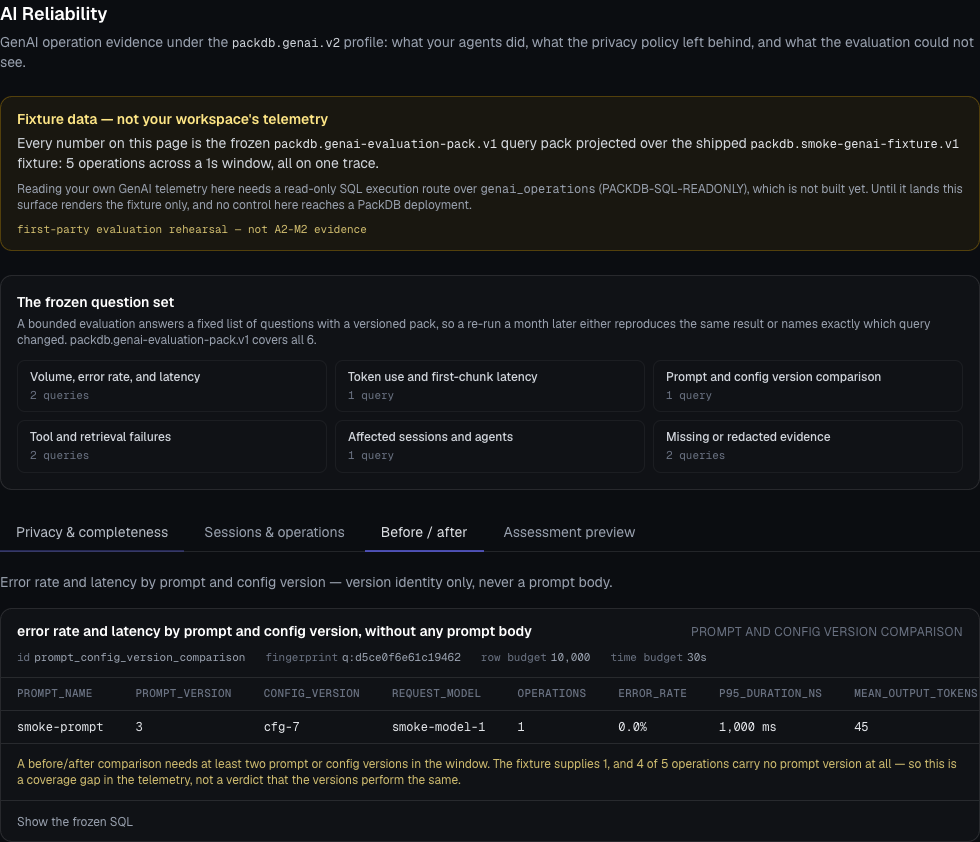
- Prompt and config version comparisons, without storing prompt bodies by default.
- Tool and retrieval failure candidates, with exact trace pivots.
- Affected sessions or agents, where tenant-safe identifiers exist.
- Missing or redacted evidence, stated as missing — never inferred content.
Fixture self-assessment
Inspect the sample before you schedule
We ran the frozen question pack through our shipped GenAI fixture and published the resulting sample assessment, before/after report, evidence-gap audit, and workspace captures. This is synthetic fixture material from our own self-assessment — not customer data, a live run, payment evidence, or A2-M2 exit evidence.
first-party evaluation rehearsal — not A2-M2 evidence
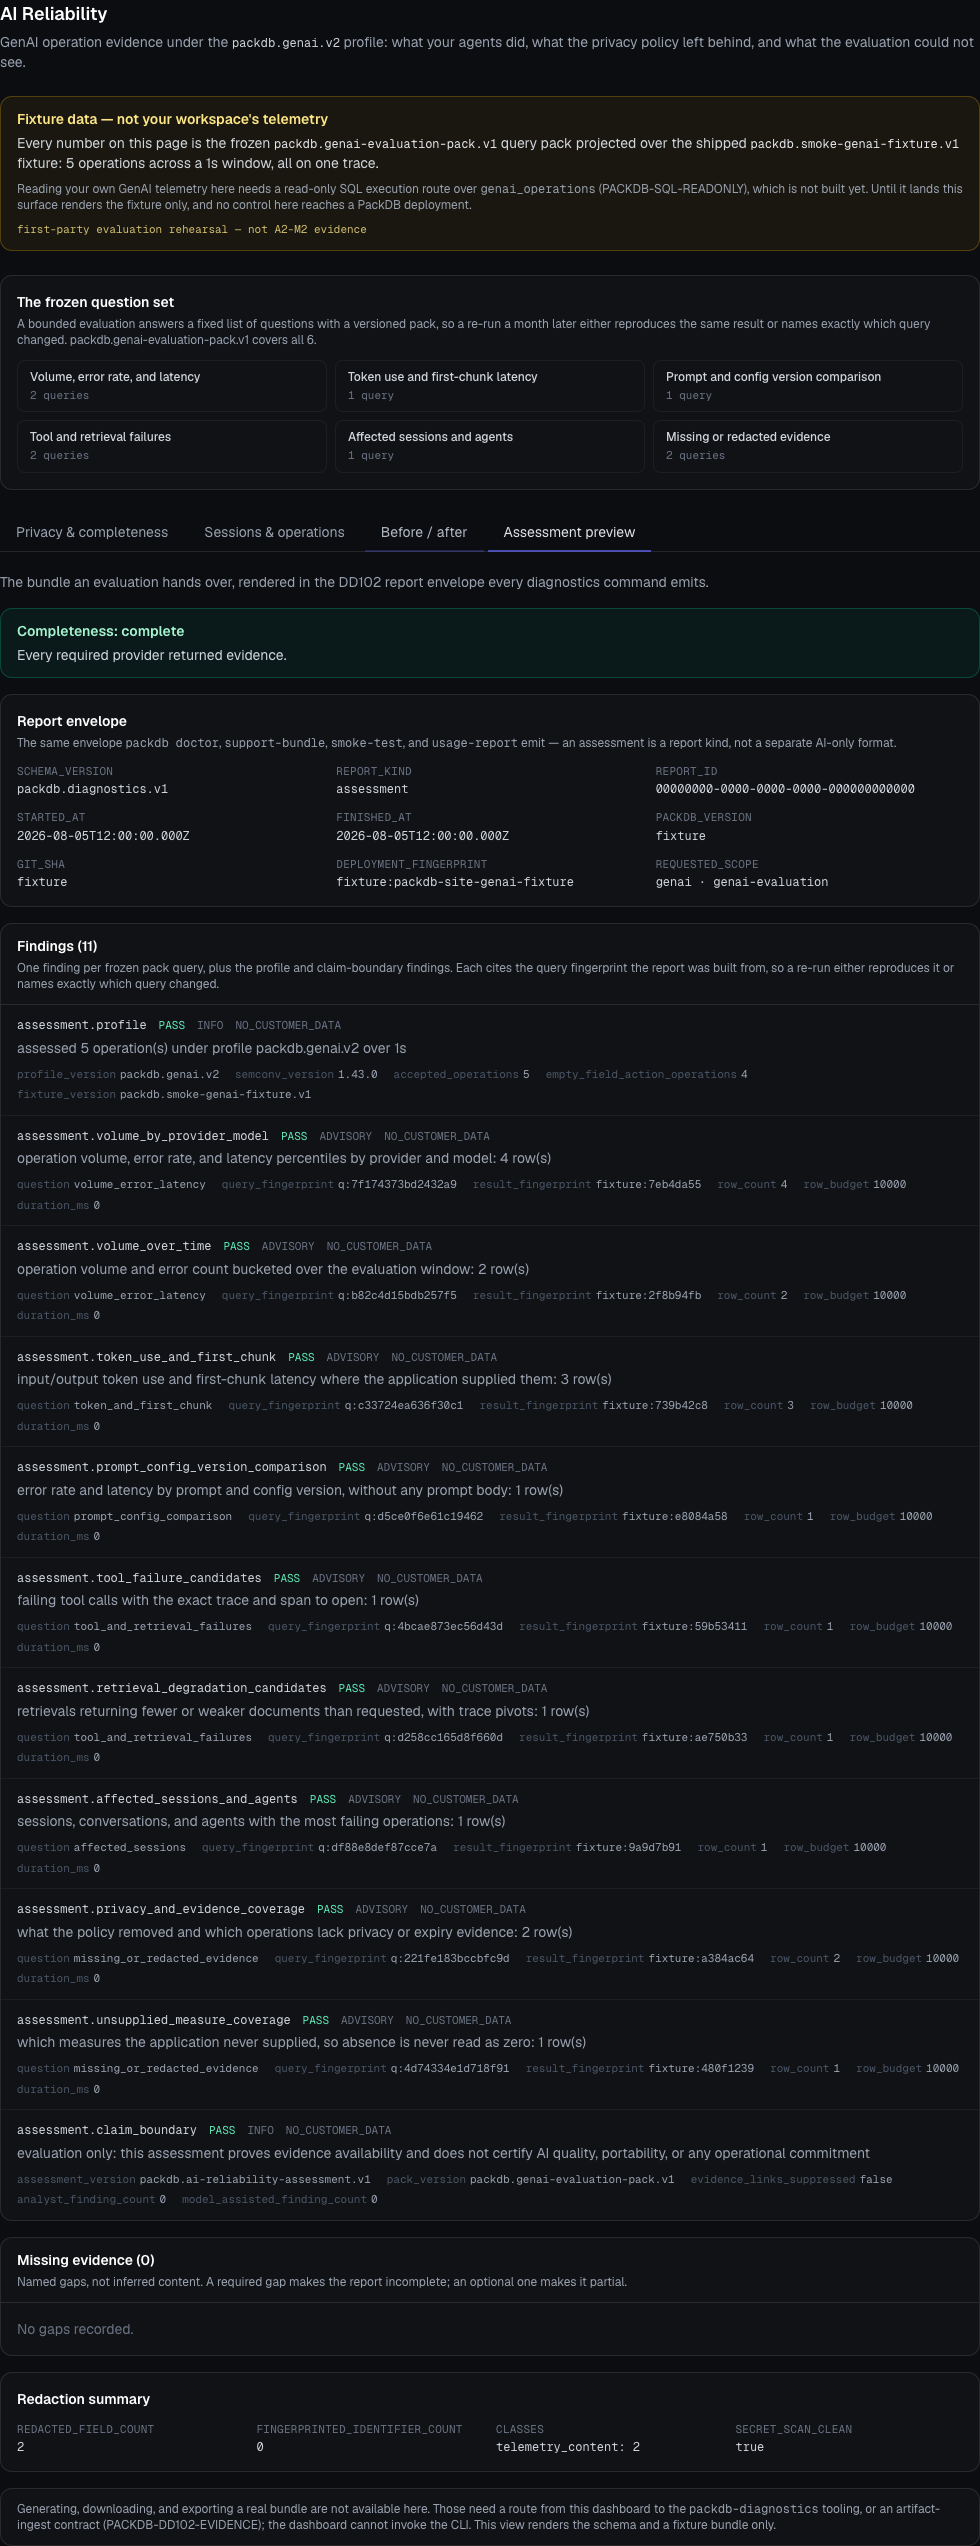
- Sample assessment
The frozen assessment envelope wrapped with fixture and first-party provenance.
- Before / after report
The version-only prompt and configuration comparison; no prompt body is present.
- Evidence-gap audit
Required report gaps and measures the fixture application did not supply.
- Before / after workspace capture
A fixture-labeled capture of the deterministic comparison surface.
- Assessment workspace capture
A fixture-labeled capture of the assessment preview surface.
- Provenance manifest
Digests, source slices, limitations, and the exact not-applicable commercial matrix.
Where the boundary sits
Stated up front so you can tell whether this engagement fits before you pay for it.
PackDB is not your system of record
The input is a customer-approved export, a sanitized fixture, or an explicitly non-authoritative shadow copy. Your source telemetry stays in your authoritative system throughout.
No production SLO
This engagement carries no production availability, durability, recovery, or migration commitment. Continuous authoritative ingestion or a dependency on this workspace for production alerting is outside the evaluation boundary.
Fixed duration, ceiling, and owner
The engagement has a fixed duration, a data-volume ceiling, a named owner, and a documented support channel — all agreed before it starts.
Privacy enforced before the write
The packdb.genai.v2 profile enforces privacy before the write-ahead log. Every report identifies the policy, profile, source window, completeness, and redactions. No prompt, response, tool, or retrieval body appears in any report.
Your artifacts are exportable, and the teardown is documented
You receive exportable assessment artifacts and a documented deletion and teardown result at the end, including any residual backend-retention interval where immediate physical erasure is unavailable.
Deterministic findings
The workspace is deterministic. An analyst may write findings, and any generated hypothesis is labeled as analyst or model interpretation — it never replaces the query result underneath it.
Scope an evaluation with us
Tell us the application, roughly how much telemetry it produces, and what you need answered. We will confirm the fit against the boundary above before quoting.
Schedule AI Evaluation